2.04 - Pinned Memory
Pinned Memory
Operating systems don't provide direct access to physical memory, programs use virtual memory which is mapped to physical memory. Virtual memory is organized into pages which enables the OS to manage them by swapping pages to and from disk when physical memory starts to run low
A given page can be in physical memory, on disk, or somewhere else. When a page can be relocated to disk it's called pageable, but we can also force memory to stay in physical memory by pinning / page-locking it
GPU and CUDA can only copy data from physical memory! So when copying data between host and device the object itself has to be pinned. In the last Streams Exercise the real Nsight profiling still showed things as synchronous is that under the hood CUDA had to use a special staging buffer to copy data from disk, to physical memory, and then finally could copy it over to CPU. This is a GPU based operation, and so there wasn't a good way to overlap this with GPU compute for the next batch.
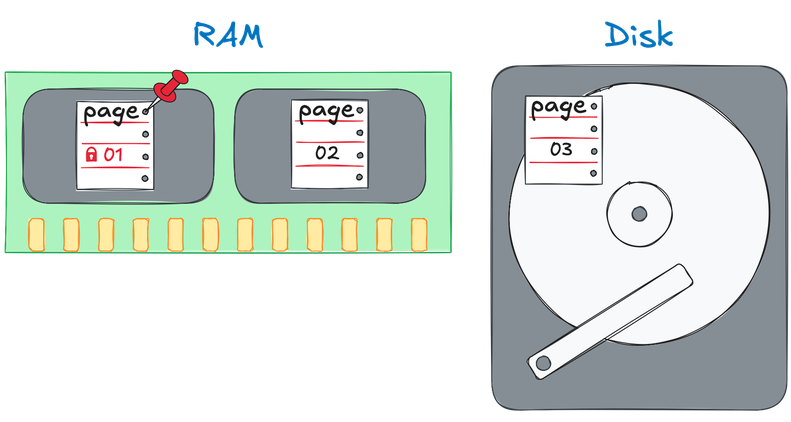
Use thrust::universal_host_pinned_vector to pin objects to RAM memory, and not on disk. When doing cudaMemcpyAsync transferring data from disk to physical memory will stop asynchronous commands and essentially turn things synchronous